Posts Tagged ‘society’
“Common sense is not so common”*…

The Enlightenment is under attack by the Left and the Right. It can only be “saved,” Eliane Glaser argues, through use of its greatest legacy: permanent critique. And then there’s AI. After summarizing the critiques from both sides, she continues…
In consequence of this pincer-movement attack, the Enlightenment’s legacy is existentially vulnerable. It makes me deeply worried as someone whose entire career has been built on trying to understand and analyse the world around me – especially a world that still tries to confine thinking women to the realms of emotion and ‘personal experience’.
I believe that Enlightenment values are essential, but that we have largely forgotten how to make a good case for them: we need to rely on shared facts, tested by experiment; a public sphere where open discussion can take place; and the belief that discussion should be founded on reasoned argument. We need, moreover, to cherish the more political values of tolerance, freedom, human rights and the common good. Advocates for artificial intelligence have the temerity to claim that large language models are ushering in a ‘second Enlightenment’ (a claim that was uncritically echoed in a paper published by the World Economic Forum last year) when what we are in fact seeing is the destruction of the Enlightenment legacy under the false banner of its name. As the historian David Bell argued in The New York Times in 2025, AI is actually ‘shedding Enlightenment values’ by simply reinforcing ‘what we already think we know.’ In The Guardian,the journalist and geopolitical risk consultant Joseph de Weck warned that ‘AI is taking us back to the dark ages’, making us lazy, and stymying independent thinking.
The evidence suggests that we are going through a rapid de-enlightenment. Newspaper circulations, attention spans, and trust in forms of agreed knowledge are in freefall. Misinformation, disinformation and deepfakes are gaining ground. If we let go of the valuable aspects of the Enlightenment project, we open ourselves up to a world of AI blather, ‘my truth’ pronouncements, wobbly sentiment and unchecked power.
My unease with this parlous state of affairs has provoked me to go back and rethink the Enlightenment and what it has to offer. But, rather than unthinkingly recouping it as a mission, I want instead to tease out and weigh up its merits, to discern with nuance what is still fit for our times. I want to ask if it is possible to rescue the Enlightenment’s rallying power, and if it’s worth defending what the combined forces of Left and Right are coming together to attack. Are the Enlightenment’s deficiencies barnacles on an old ship, or integral to its design?…
And so she does. Do read on: “Flickering Enlightenment,” from @elianeglaser.bsky.social in @aeon.co.
* Voltaire
###
As we reclaim reason, we might spare a thought for a glorious product of the Enlightenment, Joseph Haydn; he died on this date in 1809. A composer of the Classical period, he was pivotal in the evolution of chamber music forms like the string quartet and piano trio, and is known as the “Father” of both the symphony and sonata forms. Haydn was a friend and mentor of Mozart, and a teacher of Beethoven; indeed, the Haydn, Mozart and Beethoven trio are sometimes referred to as the “First Viennese School.”
Schonberg wrote that Haydn “was the Classic performer par excellence, and in his long life, from 1732 to 1809, he grew up with the new musical ideas and, more than any one man, shaped them.”
“Adaptation and mitigation are two sides of the same coin. If mitigation is about preventing the unmanageable, adaptation is about managing the unavoidable.”*…

Adapting to climate change is quickly becoming part of everyday life. Nabig Chaudhry outlines seven trends we’re seeing for 2026 and beyond…
Within the climate and scientific communities, there’s growing concern about how quickly the world is approaching (and may exceed) 2°C of warming. 2024 was the first calendar year in which global average temperature exceeded 1.5°C above preindustrial levels. The impacts of rapid warming are becoming harder to miss: The climate is changing quickly almost everywhere, local and global climate risks are growing, progress on mitigation has become more politically constrained and uncertain, and many of our systems and policies aren’t prepared for the conditions ahead.
Growing climate risk is increasing the demand for new technologies, tools, strategies, and ways of thinking about climate adaptation. Since publishing our Insights on Climate Adaptation in 2025 report, the practice of climate adaptation has continued to develop, as more people, communities, organizations, and institutions work to understand and respond to climate risks.
People use different language to describe climate adaptation (including climate resilience), but the work centers on helping people, communities, and organizations manage the risks of a changing climate. Those activities are expanding, and we can already see signs. For example, new funding and investment vehicles are emerging, such as Tailwind Futures, and adaptation is receiving more dedicated space at major climate convenings, including The Adaptation Forum, a co-hosted gathering of thought leaders in the adaptation space during Climate Week NYC 2025.
In my role as Director of Climate Adaptation Research at Probable Futures and through my PhD program at the University of California, Berkeley, I speak with experts, read emerging research, and study adaptation developments every day. Through these conversations and insights, I’ve reflected on which adaptation trends are likely to emerge and strengthen…
Chaudhry npacks seven different trends; here, let me highlight two. The first is one that (Roughly) Daily has visited before, insurance…
Elevating insurance as a force in adaptation planning, policy, and behavior
Insurance is a valuable adaptation tool, as it can transfer risk, support recovery after climate shocks, and help signal where danger is increasing through premiums, deductibles, coverage limits, or insurer retreat. It can also shape incentives, because the way risk is priced can influence whether and how people and institutions reduce exposure, strengthen buildings, or avoid certain kinds of development.
As climate risks grow, damage to property and homes becomes more frequent and severe. Property owners are experiencing those shocks both physically (flooding, fire, wind damage, etc.) and financially as insurance markets adjust and recalibrate in response to changing probabilities and severities. Insurance markets have begun reflecting climate risk, and those changes are starting to influence where and how people build homes and infrastructure, where they invest in property, and where they choose to live.
A useful example of how insurance is beginning to influence adaptation efforts in the public sphere is Strengthen Alabama Homes, a program of the Alabama Department of Insurance. The program provides grants to help homeowners retrofit their homes and roofs to reduce wind damage from extreme winds and storms. Homeowners who participate can receive discounts on the wind portion of their homeowner’s insurance premium, which makes insurance not only a tool for recovery but also a tool for encouraging adaptation before exposure occurs.
Insurance pricing is one way climate risk is made visible, priced, and acted on through adaptation. I expect that insurance will increasingly influence adaptation planning, policy, and behavior, not only by helping people recover after climate shocks, but by shaping the choices people make before those shocks occur. The development of the insurance industry will therefore be an important factor in adaptation. If insurers become a source not only of risk pricing but also of risk information, adaptation guidance, and incentives to reduce risk, they could help more people act before losses occur. But that would require a meaningful shift in the role of insurance companies, from mainly pricing and transferring risk to also helping people reduce it…
The second goes to the contentious topic of geoengineering…
Expanding debate around the role of climate intervention
As warming continues, risks keep growing. We have more, clearer, worrisome signals that irreversible change, tipping points, and local climate changes so severe that adaptation is impractical if not impossible, are not far off. In response, people and institutions are starting new conversations about global-scale responses. One of those responses is climate intervention, sometimes called geoengineering.
Climate intervention generally refers to intentional efforts to alter Earth’s systems in order to counteract some of the effects of climate change. It can include approaches that remove carbon dioxide from the atmosphere, as well as approaches that reflect a portion of sunlight back into space, such as stratospheric aerosol injection.
Its relationship to adaptation is uneasy, but important. If climate intervention is, at its core, an effort to manage the otherwise unmanageable risks of global climate change, then is it another tool for adapting to climate change, or is it something fundamentally different? There is no consensus, and there may never be, not least because global action will cause uneven responses locally. We don’t know much about the potential impacts of some climate interventions, how they could affect different regions unequally, or what long-term consequences they may have for Earth’s climate and natural systems.
There are good reasons to have informed conversations and do fundamental research on intervention. People with adaptation expertise can help explore, illuminate, and explain what climate intervention could mean for society and nature. There are also likely to be benefits for adaptation professionals to participate in these conversations and research projects. Even if climate intervention is never widely deployed, the debate itself may shape adaptation thinking, climate policy, research funding, public trust, and international governance.
Climate change requires people to consider risks and options, whether for mitigation, adaptation, or intervention. Treating strategies for managing the rate, pace, and impacts of climate change as distinct and separate is unlikely to lead to good outcomes. I am hopeful that there will be more collaboration across these new fields as society faces new challenges that have a common root cause. This may include more discussion about how these technologies should be governed, whether they should receive more investment, and whether climate intervention is a possible third leg alongside mitigation and adaptation…
Eminently worth reading in full: “The near-term future of climate adaptation: emerging trends.”
* U. N. Environmental Program
###
As we prepare, we might recall (wistfully) that it was on this date in 1942 that Bing Crosby, with the Trotter Orchestra and the Darby Singers, recorded Irving Berlin’s song, “White Christmas.” According to the Guinness Book of World Records, this version is the best-selling single of all time with an excess of 50 million copies sold worldwide. (In fact, the version most often heard today is not the original. After frequent use, the master had become damaged, so on March 18, 1947, Crosby re-recorded the holiday hit.)

“Privacy is rarely lost in one fell swoop. It is usually eroded over time, little bits dissolving almost imperceptibly until we finally begin to notice how much is gone.”*…

… And now, indeed, we’re beginning to notice. Hana Lee Goldin surveys the state of play– who’s buying our personal information, what they’re using it for, and how the system works behind the screen– and considers our options…
Sometime in the mid-2000s, most of us started handing over pieces of ourselves to the internet without giving the exchange a second thought. We created email accounts, signed up for social media, bought things online, downloaded apps, swiped loyalty cards, connected fitness trackers, stored photos in the cloud, and agreed to terms of service that almost none of us have ever read in full. We did this thousands of times over two decades and counting, and each interaction felt small enough to be inconsequential.
But the accumulation is enormous. More than 6 billion people now use the internet, and each one makes an estimated 5,000 digital interactions per day. Most of those interactions happen without our conscious awareness: a GPS ping, a page load, an app opening, a browser cookie refreshing, a device checking in with a cell tower. The average person in 2010 made an estimated 298 digital interactions per day. In fifteen years, that number multiplied more than sixteenfold. Those digital interactions produce records that can persist indefinitely, stored, copied, indexed, bought, sold, and combined with other records to build profiles of extraordinary detail.
If we’ve been online since the late 1990s or early 2000s, our data footprint can include social media accounts we’ve created, online purchases we’ve made, forums we’ve posted in, loyalty cards we’ve used, and apps we’ve installed going back decades. Some of that information lives on platforms we’ve long forgotten. Some of it was collected by companies that have since been acquired or dissolved, with our data potentially passing to successor entities we’ve never heard of. The digital life most of us have been living for 15 to 25 years has produced a layered, evolving archive that only grows more valuable to the people who buy and sell it as time goes on.
Most of us sense that something is off about all of this. In a 2023 survey, Pew Research found that roughly eight in ten Americans feel they have little to no control over the data companies collect about them, 71% are concerned about government data use, and 67% say they understand little to nothing about what companies are doing with their personal information. The concern is real and widespread. And so is the feeling of helplessness: 60% of Americans believe it’s impossible to go through daily life without having their data tracked. The unease is there. What’s missing is a clear picture of what’s happening on the other side of the transaction…
[Goldin explains what data is being collected and shared, and by whom; how the data is managed and trafficked; how its being used (by insurance and financial companies, employers and landlords, retailers, AI companies, governments, and criminals); and how “inferred” data is used to augment the “hard” data. It’s chilling. She then puts the issue into context, and discusses we we can– and cannot– do about it…]
… The philosopher Helen Nissenbaum has a framework for what’s happening here: contextual integrity. The idea is that privacy isn’t about secrecy. We share information willingly all the time, when the context fits. We tell our doctor about a health condition because we expect that information to stay within the medical relationship. We search for symptoms on a health website because we assume that search won’t follow us into an insurance application. In the current data economy, that’s exactly the kind of boundary that dissolves, because the company collecting the data and the company buying it are operating in completely different contexts.
This is an information literacy problem as much as a privacy problem. Information literacy is usually framed around consumption: evaluating sources, questioning claims, recognizing bias in what we read and watch. But every time we interact with a digital service, we’re also producing information: generating a record that will be read, interpreted, scored, and acted on by organizations we may never interact with directly. Many of us have gotten better at questioning the information that comes at us: checking sources, noticing bias, and recognizing when something is trying to sell us a conclusion. But we haven’t developed equivalent habits around the information that flows from us: where it goes after we hand it over, who reads the record, what incentives they have, and what conclusions they draw. The gap between what we think we’re consenting to and what we’ve agreed to in practice is where the real exposure lives, and the system is designed to keep that gap invisible.
One of the reasons the “so what” question is hard to answer with action is that opting out of data collection often means opting out of participation. Declining a social media platform’s terms of service means not using the platform. Refusing location permissions can mean losing access to navigation, ride-sharing, weather, and delivery apps. Choosing not to create an account can mean paying more, seeing less, or being locked out of services that have become essential infrastructure for work, communication, healthcare, banking, and education.
The architecture of digital consent treats data sharing as a binary: agree to the terms or don’t use the product. There’s rarely a middle option that allows us to use a service while limiting what data gets collected and where it goes. The result is that the “choice” to share data often functions as a condition of entry into daily life rather than an informed negotiation. We’re not handing over data because we’ve weighed the tradeoff and decided it’s fair. We’re handing it over because the alternative is exclusion from services we rely on.
This is the structural context behind the Pew Research Center finding that more than half of Americans believe it’s impossible to go through daily life without being tracked. For many of us, it isn’t possible, at least not without significant inconvenience or sacrifice. The question isn’t whether we can avoid data collection entirely, because for the vast majority of people who participate in modern life, the answer is no. The question is whether we can make more informed decisions within the constraints we’re operating in, and whether the system can be pushed – through regulation, through market pressure, through better tools – toward something more transparent.
California’s Delete Act, which took effect in January 2026, is the strongest example of what’s emerging. It created a platform called DROP (Delete Request and Opt-Out Platform) that lets California residents submit a single deletion request to every registered data broker in the state. Brokers are required to process those requests, maintain suppression lists to prevent re-collection, and check the platform regularly for new requests. The European Union’s GDPR provides similar individual rights, and a handful of other U.S. states have enacted their own privacy laws with varying levels of protection. But the coverage is uneven: what’s available to a California or EU resident may not extend to someone in a state without comparable legislation.
Some services now automate parts of the opt-out process, submitting removal requests to dozens of brokers on our behalf. These can’t erase the data trail entirely, but they can narrow what’s actively available for sale.
Beyond deletion, there are smaller choices that reduce how much new data we generate. We can audit which apps have permission to track our location or access our contacts, since a surprising amount of behavioral data comes from apps that don’t need those permissions to function. We can treat “sign in with Google” and “sign in with Facebook” buttons as what they are: data-sharing agreements that can link a new service to an existing profile. And we can glance at the first few lines of a privacy policy before agreeing, looking for some version of “we may share your information with our partners,” where “partners” just means anyone willing to pay.
Most of us don’t read privacy policies, and the policies aren’t built to be read. They average thousands of words of dense legal language filled with terms like “legitimate interest,” “data processor,” and “de-identified data.” Studies consistently put them at a late high school to early college reading level (grade 12 to 14), but the difficulty goes beyond reading level: the concepts are abstract, the volume of agreements we encounter is enormous, and the design of the consent process itself pushes us through as fast as possible. Pre-checked boxes, auto-scrolling agreement windows, “accept all” buttons positioned prominently while “customize settings” options sit behind additional clicks. These are dark patterns, design choices that make the path of least resistance the path of maximum data sharing.
The result is a gap between the moment we share a piece of information and the moment that information shapes a decision about our lives. We don’t connect the app to the insurance premium or the loyalty card to the rental application because the chain of custody between them is long, complex, and designed to stay out of view.
The same critical thinking we’ve learned to apply to the information flowing toward us (checking sources, questioning claims, looking for bias) applies to the information flowing from us: who’s collecting this, what will they do with it, who else will see it, and what did we agree to? The difference is that in the data economy, we’re the product being evaluated, and the questions are being asked about us rather than by us.
So can we get it back? Not entirely. Data that’s already been collected, copied, sold, and processed across multiple systems can’t be fully recalled. What we can do is reduce what’s actively available for sale, slow the flow of new data going forward, and take advantage of legal tools that didn’t exist a few years ago. The archive of our past digital lives is too distributed to undo, but the file is still being written, and we have more say over the next page than we did over the last twenty years of them.
So what if they have our data? The tradeoff extends well beyond better ads. It reaches into the prices we’re charged, the credit we’re offered, the jobs we’re considered for, the insurance premiums we pay, the AI systems trained on our behavior, the accuracy of the profiles used to make decisions about our lives, and the degree to which government agencies can monitor our movements without a warrant. Every new service we sign up for, every permission we grant, and every terms-of-service agreement we accept adds another layer to that file. We can’t close the file entirely, but we can make more informed decisions about what goes into it next…
Eminently worth reading in full: “So What if They Have My Data?“
See also: “Why Do We Care So Much About Privacy?” (source of the image above) in which Louis Menand suggests that our concern should be with the “weaponization” of data…
* Daniel J. Solove, Nothing to Hide: The False Tradeoff Between Privacy and Security
###
As we reinforce our rights, we might recall that it was on this date in 1996 that the internet-as-we’ve-come-to-know-it broke big into the mainstream: Yahoo! launched the national campaign that asked “Do You Yahoo?” advertising its web-based search service on national television. The campaign was created by ad agency Black Rocket and Yahoo Marketing Head Karen Edwards (whose many awards for the work include a seat in the Advertising Hall of Achievement).
An early spot from the campaign…
“The present is pregnant with the future”*…

The estimable Tim O’Reilly uses scenario planning to create an insightful look at AI, our futures, and the choices that will define them…
We all read it in the daily news. The New York Times reports that economists who once dismissed the AI job threat are now taking it seriously. In February, Jack Dorsey cut 40% of Block’s workforce, telling shareholders that “intelligence tools have changed what it means to build and run a company.” Block’s stock rose 20%. Salesforce has shed thousands of customer support workers, saying AI was already doing half the work. And a Stanford study found that software developers aged 22 to 25 saw employment drop nearly 20% from its peak, while developers over 26 were doing fine.
But how are we to square this news with a Vanguard study that found that the 100 occupations most exposed to AI were actually outperforming the rest of the labor market in both job growth and wages, and a rigorous NBER study of 25,000 Danish workers that found zero measurable effect of AI on earnings or hours?
Other studies could contribute to either side of the argument. For example, PwC’s 2025 Global AI Jobs Barometer, analyzing close to a billion job ads across six continents, found that workers with AI skills earn a 56% wage premium, and that productivity growth has nearly quadrupled in the industries most exposed to AI.
This is exactly the kind of contradictory, uncertain landscape that scenario planning was designed for. Scenario planning doesn’t ask you to predict what the future will be. It asks you to imagine divergent possible futures and to develop a strategy that improves your odds of success across all of them. I’ve used it many times at O’Reilly and have written about it before with COVID and climate change as illustrative examples. The argument between those who say AI will cause mass unemployment and those who insist technology always creates more jobs than it destroys is a debate that will only be resolved by time. Both sides have evidence. Both are probably right at some level. And both framings are not terribly helpful for anyone trying to figure out what to do next…
[O’Reilly explains the scenario approach, then applies it to our future with AI (see the image above), astutely assessing the conflicting signals that we’ve experiencing; he explores the “robust strategy” for our uncertian future (strategic choices that make sense regardless of which future unfolds); then he concludes…
… I’ll return to the theme that I sounded in my book WTF? What’s the Future and Why It’s Up To Us.
Every time a company uses AI to do what it was already doing with fewer people, it is making a choice for the lower half of the scenario grid. Every time a company uses AI to do something that wasn’t previously possible, to serve a customer who wasn’t previously served, to solve a problem that wasn’t previously solvable, it is making a choice for the upper half. These choices compound, for good or ill. An economy that uses AI primarily for efficiency will slowly hollow itself out.
Looking at the news from the future, both sets of signals are present. The question is which will dominate. AI will give us both the Augmentation Economy and the Displacement Crisis, in different measures in different places, depending on the choices we make.
Scenario planning teaches us that we don’t have to predict which future we’ll get. We do have to prepare for a very uncertain future. But the robust strategy, the one that works across every quadrant, is to focus on doing more, not just doing the same with less, and to find ways that human taste still matters in what is created. As long as there is unmet demand, as long as there are problems we haven’t solved and people we haven’t served, AI will augment human work rather than replacing it. It’s only when we stop looking for new things to do that the machines come for the jobs…
Eminently worth reading in full. Indeed, speaking as a long-time scenario planner, your correspondent can only wish that everyone who wields “scenarios” applies the approach as appropriately, adriotly, and acutely as Tim has: “Scenario Planning for AI and the ‘Jobless Future‘,” from @timoreilly.bsky.social.
* Voltaire
###
As we take the long view, we might send formative birthday greetings to Mark Pinsker; he was born on this date in 1923. A mathematician, he made impoprtant contributions to the fields of information theory, probability theory, coding theory, ergodic theory, mathematical statistics, and communication networks. This work, which helped lay the foundation for AI-as-we-know-it, earned him the IEEE Claude E. Shannon Award in 1978, and the IEEE Richard W. Hamming Medal in 1996, among other honors.

“Everything is destroyed by its own particular vice: the destructive power resides within”*…
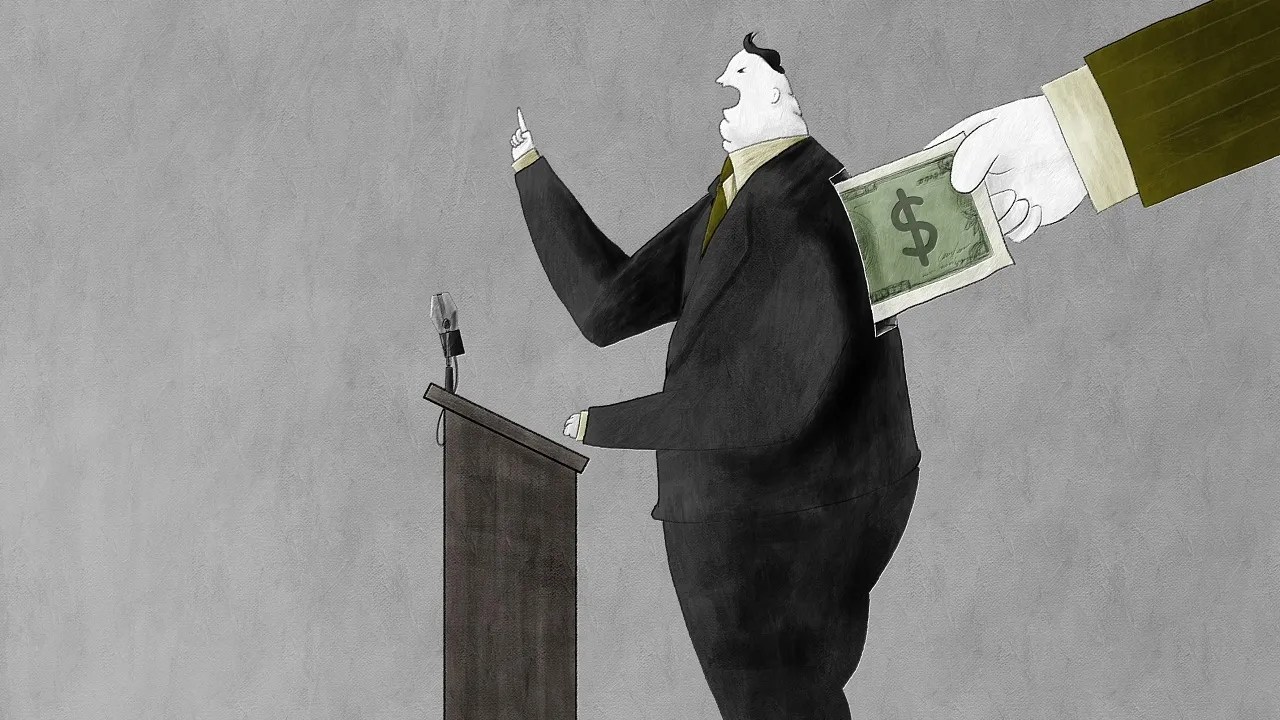
Government graft in the U. S. has a long (and unbroken) history; but there have been especially corrupt periods, for instance in the Jacksonian era and the Gilded Age… and again today.
Profiteering and insider trading, “pay-to-play”/influence peddling, foreign emoluments, conflicts of interest, regulatory and policy favors, purchased pardons (and commutations)– we’ve got it all, and at epic levels.
The estimable Cory Doctorow uses a telling comparison to drill down on one of the dominant strands: Trump’s (ironic) campaign to fight (what he identifies as) corruption…
… It’s a story about boss-politics anti-corruption, in which anti-corruption is pursued to corrupt ends.
From 2012-2015, Xi Jinping celebrated his second term as the leader of China with a mass purge undertaken in the name of anti-corruption. Officials from every level of Chinese politics were fired, and many were imprisoned. This allowed Xi to consolidate his control over the CCP, which culminated in a rule-change that eliminated term-limits, paving the way for Xi to continue to rule China for so long as he breathes and wills to power.
Xi’s purge exclusively targeted officials in his rivals’ power-base, kneecapping anyone who might have blocked his power-grab. But just because Xi targeted his rivals’ princelings and foot-soldiers, it doesn’t mean that Xi was targeting the innocent. A 2018 paper by an economist (Peter Lorentzen, USF) and a political scientist (Xi Lu, NUS) concluded that Xi’s purge really did target corrupt officials.
The authors reached this conclusion by referencing the data published in the resulting corruption trials, which showed that these officials accepted and offered bribes and feathered their allies’ nests at public expense.
In other words, Xi didn’t cheat by framing innocent officials for crimes they didn’t commit. The way Xi cheated was by exclusively targeting his rivals’ allies. Lorentzen and Lu’s paper make it clear that Xi could easily have prosecuted many corrupt officials in his own power base, but he left them unmolested.
This is corrupt anti-corruption. In an environment in which everyone in power is crooked, you can exclusively bring legitimate prosecutions, and still be doing corruption. You just need to confine your prosecutions to your political enemies, whether or not they are more guilty than your allies (think here of the GOP dragging the Clintons into Epstein depositions).
14 years later, Xi’s anti-corruption purges continue apace, with 100 empty seats at this year’s National People’s Congress, whose former occupants are freshly imprisoned or awaiting trial.
I don’t know the details of all 100 prosecutions, but China absolutely has a corruption problem that goes all the way to the upper echelon of the state. I find it easy to believe that the officials Xi has targeted are guilty – and I also wouldn’t be surprised to hear that they are all supporters of Xi’s internal rivals for control of the CCP.
As the Epstein files demonstrate, anyone hoping to conduct a purge of America’s elites could easily do so without having to frame anyone for crimes they didn’t commit (remember, Epstein didn’t just commit sex crimes – he was also a flagrant financial criminal and he implicated his network in those crimes).
It’s not just Epstein. As America’s capital classes indulge their incestuous longings with an endless orgy of mergers, it’s corporate Habsburg jaws as far as the eye can see. These mergers are all as illegal as hell, but if you fire a mouthy comedian, you can make serious bank.
And if you pay the right MAGA chud podcaster a million bucks, he’ll grease your $14b merger through the DoJ.
And once these crooks merge to monopoly, they embark on programs of lawlessness that would shame Al Capone, but again, with the right podcaster on your side, you can keep on “robbing them blind, baby!”
The fact that these companies are all guilty is a foundational aspect of Trumpism. Boss-politics antitrust – and anti-corruption – doesn’t need to manufacture evidence or pretexts to attack Trump’s political rivals. When everyone is guilty, you have a target-rich environment for extorting bribes.
Just because the anti-corruption has legit targets, it doesn’t follow that the whole thing isn’t corrupt…
On the practice of selective enforcement and prosecution: “Corrupt anticorruption,” from @pluralistic.net.web.brid.gy.
For thoughts on what we can do about all of this, see “Building political integrity to stamp out corruption: three steps to cleaner politics” (source of the image above)
* Menander
###
As we decide on disinfectants, we might recall that it was on this date in 37 CE, following the death of Tiberius, that the Roman Senate annulled Tiberius’ will and confirmed Caligula, his grandnephew, as the third Roman emperor. (Tiberius had willed that the reign should be shared by his nephew [and adopted son] Germanicus and Germanicus’ son, Caligula.)
While he has been remembered as the poster boy for profligacy and corruption, Caligula (“Little Boots”) is generally agreed to have been a temperate ruler through the first six months of his reign. His excesses after that– cruelty, self-dealing, extravagance, sexual perversity– are “known” to us via sources increasingly called into question.
Still, historians agree that Caligula did work hard to increase the unconstrained personal power of the emperor at the expense of the countervailing Principate; and he oversaw the construction of notoriously luxurious dwellings for himself. In 41 CE, members of the Roman Senate and of Caligula’s household attempted a coup to restore the Republic. They enlisted the Praetorian Guard, who killed Caligula– the first Roman Emperor to be assassinated (Julius Caesar was assassinated, but was Dictator, not Emperor). In the event, the Praetorians thwarted the Republican dream by appointing (and supporting) Caligula’s uncle Claudius as the next Emperor.

You must be logged in to post a comment.